A Brief On Elastic Search
Hello, I’m Nripesh
I am an aspiring programmer, continuously learning and building projects one step at a time.
This blog will serve as a record of my journey, where I document the coding challenges I encounter each week and the solutions I work towards. My intention is not only to track my own growth but also to provide clarity for others who may face similar difficulties.
What you can expect here:
Weekly summaries of the issues I struggled with
Solutions, explanations, and key insights I gained from them
References and links to helpful resources, documentation, or my GitHub repositories
Occasional notes on personal projects I am developing
I am still in the early stages of my learning path and have much to improve, but I approach each challenge with confidence and persistence. This space is both a personal archive and an attempt to contribute—however modestly—to the wider learning community.
If you are also navigating the world of programming, I welcome you to connect and share perspectives.
The query shown uses ILIKE '%laptop%' to search inside text fields:
SELECT * FROM products
WHERE name ILIKE '%laptop%'
OR description ILIKE '%laptop%';
While this works for small datasets, it becomes inefficient in real production systems. When a pattern begins with %, the database cannot use standard indexes, forcing it to scan every row in the table to check for a match. As the dataset grows to millions of records, this results in full table scans, high CPU usage, and slow response times. Additionally, traditional SQL pattern matching only performs simple substring searches and lacks capabilities such as relevance ranking, typo tolerance, and language-aware search.
This is where Elasticsearch becomes valuable. Elasticsearch is a distributed search engine built for full-text search at scale. Instead of scanning rows, it creates an inverted index that maps words to the documents containing them, allowing queries to be executed extremely quickly even across large datasets. It also provides advanced features like relevance scoring, fuzzy search, autocomplete, and horizontal scalability.
For modern production backends where users frequently search through large datasets, relying on SQL ILIKE queries is not practical. Dedicated search systems like Elasticsearch are designed specifically to handle these workloads efficiently.
Inverted Index
An inverted index is the fundamental concept that makes modern search engines like Elasticsearch extremely fast.
Instead of searching through every document each time a query is made, the system builds a structure that keeps track of which words appear in which documents.
In a traditional database search, the system often needs to scan rows and check each text field to see if it contains the search term. As the amount of data grows, this approach becomes slower because the database has to inspect many records.
An inverted index solves this by organising data around words rather than documents.
For every word that appears in the dataset, the system maintains a list of the documents that contain that word. When a user searches for a term, the search engine simply looks up that word in the index and immediately finds the relevant documents instead of scanning everything.
Elasticsearch Features:
1. Term Frequency (TF) Term frequency measures how many times a search term appears within a document. The idea is that if a word appears more frequently in a document, the document is more likely to be relevant to the query. For example, if the word “laptop” appears several times in a product description, that document will generally rank higher than one where the word appears only once.
2. Document Frequency (DF) Document frequency refers to how many documents in the entire dataset contain a particular term. Words that appear in many documents (such as common terms) are usually less useful for distinguishing relevance. Search engines use this information to give more importance to rarer and more informative words.
3. Document Length Document length considers how long the document is compared to others. If a document is very long, a term appearing multiple times might not necessarily mean it is highly relevant. Search engines normalise scores so that shorter documents are not unfairly disadvantaged or longer ones overly favoured.
4. Field Boosting Field boosting allows certain fields to be considered more important than others during ranking. For instance, in a product search system, matches in the product title may be given more weight than matches in the description, ensuring that the most meaningful results appear first.
It allows for a fault tolerance as well. For example: in the below given example, the elasticsearch recommends topics with 'trending' and not 'treding' as it can analyse what was the likely intended term.
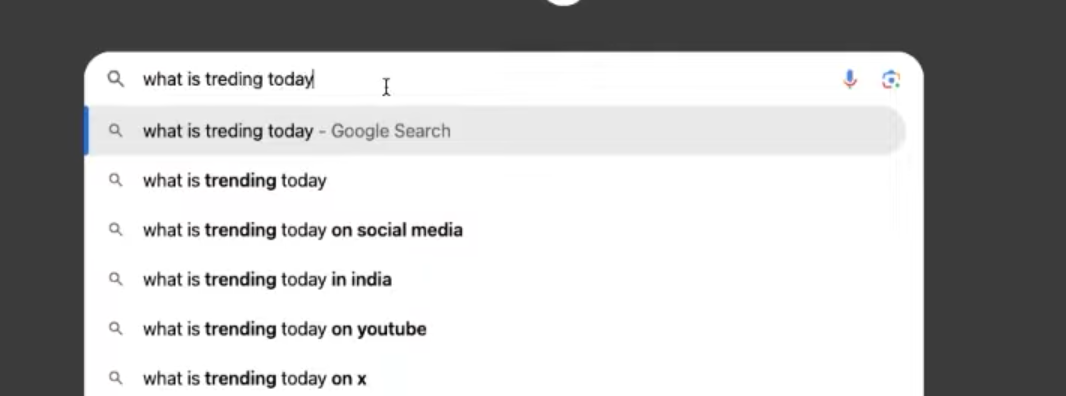
Together, these factors help search engines produce more accurate and meaningful search rankings rather than simply returning documents that contain the search keyword.
Conclusion:
Efficient search is a cornerstone of modern backend systems, and moving beyond basic queries to tools like Elasticsearch enables both speed and relevance at scale. Understanding these concepts lays the groundwork for building robust applications—next, we’ll look at how to make those systems resilient through effective error handling in the backend.